Running experiments#
Execution#
job = ck.submit_experiments(cut_experiment, backend=fake)
expectation_values = ck.estimate_expectation_values(job.result())
submit_experiments() returns a QCutJob as soon as everything is
submitted, and result() waits for the results. The job is shaped like a Qiskit
job, so it can be checked on while the run is under way:
job.job_ids()          # every backend job, in submission order
job.status()           # one JobStatus for the whole experiment
job.partial_results()  # per batch: wave, job id, status, circuits, shots, result
run_experiments() takes the same arguments and is the same as
submit_experiments(...).result().
estimate_standard_errors() gives an upper bound on each value’s shot noise,
shaped like the values:
standard_errors = ck.estimate_standard_errors(job.result())
It covers sampling error only, not device noise.
The cost of an experiment run can be checked before submission:
print(ck.estimate_run(cut_experiment, shots=4096, max_batch_size=40))
Experiment will run 144 circuits in 4 jobs with a total of 589824 shots. See the
returned object for the breakdown.
{'job1': JobEstimate(circuits=40, shots=4096),
 'job2': JobEstimate(circuits=40, shots=4096), ...}
Exact for non-communicating runs. Runs whose wire cuts communicate get executed in waves so that each wave after the first spends its shots on what the one before it measured. For these jobs the circuit count is exact and job and shot counts are estimates.
The job submits those waves itself. The first goes out before
submit_experiments() returns, and a thread of the job’s own submits each later
one as soon as the one before it is in, so nothing has to keep polling for the run to
move on. job.cancel() cancels what is still queued and submits no further waves.
backend takes a Qiskit backend, a V2 sampler, or anything else shaped like a
backend, which is what lets e.g. fiqci-ems run the experiment:
from fiqci.ems import FiQCISampler

job = ck.submit_experiments(
    cut_experiment, backend=FiQCISampler(backend, mitigation_level=1)
)
The same goes for ParallelBackend, which spreads an experiment over
several devices: see Running on several backends.
Every batch is submitted before any of it is collected, so a run queues all its jobs at
once. max_batch_size bounds how many circuits go in one, and a target that
batches on its own account is given that same size so it does not split a batch again.
run_options is passed on to every run call for anything else the target
takes.
Note that qiskit.primitives.StatevectorSampler cannot be used since circuits
from QCut contain mid-circuit measurements and that sampler refuses those.
qiskit_aer.primitives.SamplerV2 and BackendSamplerV2 are both fine.
Comparing against the exact and noisy expectation values of the original circuit:
estimator = Estimator()
exact_expvals = [e.data.evs for e in
   estimator.run([(x) for x in zip([circuit] * len(observables), observables)]).result()
]

tr = transpile(circuit, backend=fake)

tr_obs_separate = [
   SparsePauliOp(label).apply_layout(tr.layout) for label in observables
]

fake_estimator = BackendEstimator(backend=fake)
exps = [e.data.evs for e in
   fake_estimator.run([(x) for x in zip([tr] * len(tr_obs_separate), tr_obs_separate)]).result()
]
np.set_printoptions(formatter={"float": lambda x: f"{x:0.6f}"})

print(f"QCut expectation values:{np.array(expectation_values)}")
print(f"Noisy expectation values with fake backend:{np.array(exps)}")
print(f"Exact expectation values with ideal simulator :{np.array(exact_expvals)}")
QCut expectation values:[0.763209 0.602396 0.328544 0.575471]
Noisy expectation values with fake backend:[0.846680 0.564941 0.323242 0.593262]
Exact expectation values with ideal simulator :[0.921061 0.704466 0.380625 0.764842]
As we can see QCut is able to accurately reconstruct the expectation values and be more accurate that just using the fake backend as is. (Note that since this is a probabilistic method the results vary a bit each run)
Additionally we can execute QCut using the ideal Aer simulator and see that we get (practically) exact results:
QCut expectation values:[0.920158 0.706660 0.379018 0.778012]
Several circuits at once#
Primitives run a list of cut circuits in one call and hand back the expectation
values, or the distributions, of all of them. run() and run_cut_circuit()
still do the whole sequence for a single circuit, from a marked circuit or an already
split one, and are listed in the API reference.
Probability distributions#
A cut experiment estimates expectation values, so there are no counts to tally, but the
distribution over a chosen set of qubits can still be recovered from them. Pass
qubits instead of observables:
cut_experiment = ck.get_experiment_circuits(cut_circuit, qubits=[0, 1])
job = ck.submit_experiments(cut_experiment, shots=4096, backend=sim)

probs = ck.estimate_probabilities(job.result())
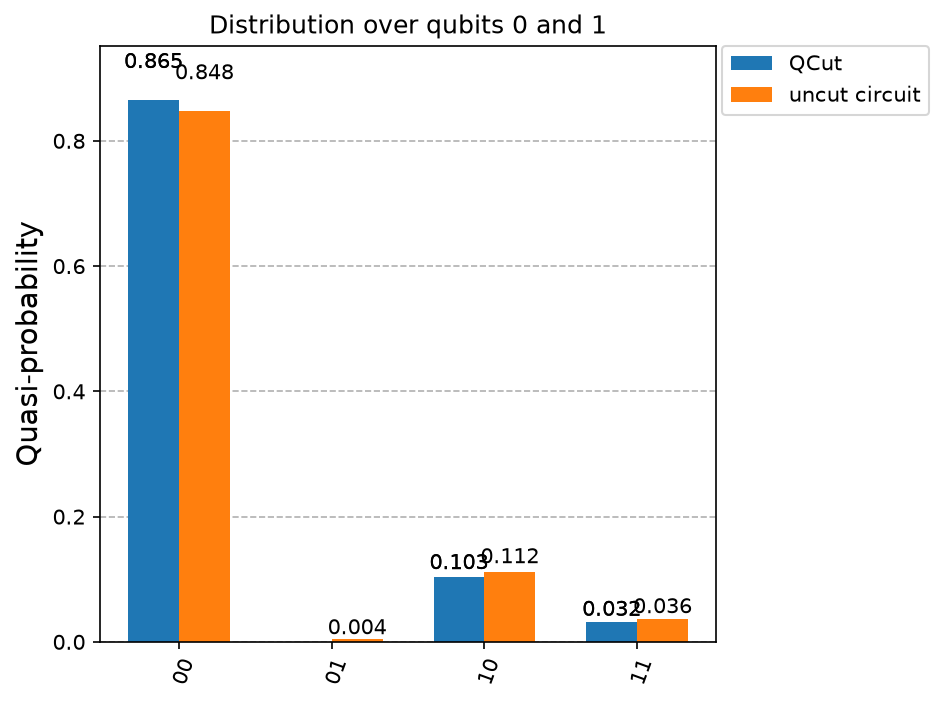
{'00': 0.8658, '01': -0.0024, '10': 0.1041, '11': 0.0324}
run() and run_cut_circuit() take qubits in the same way, and hand
back the distribution rather than expectation values.
The whole distribution needs one measurement setting, so the experiment is the size it would have been for a single observable however many qubits are asked for. See the derivation for how the distribution is reconstructed.
The result is a mapping, so it indexes and plots like a dict, and carries three views:
probs['00']                     # 0.8658
probs.quasi_probabilities()     # the same values, as a plain dict
probs.nearest_probabilities()   # closest true distribution, negatives projected away
probs.counts()                  # scaled by the shots the experiment ran at
probs.counts(shots=1000)        # or by any other shots
The three dict views report, by default, the ten most likely bitstrings. Pass top for a different
number, or top=None for all of them:
probs.quasi_probabilities(top=50)      # the fifty most likely
probs.counts(shots=1000, top=None)     # the whole distribution, as before
Note that counts() sums to shots only with top=None, and
only quasi_probabilities() gets cheaper this way since the other two project onto the
nearest physical distribution first.
Additionally you can get probabilities of a single bitstring or a marginal distribution over a subset of the qubits:
probs.top(100)               # the 100 most likely bitstrings, exactly
probs.probability_of('01')   # one bitstring, without the others
probs.marginal([0])          # a coarser distribution, summed over the rest
probs.standard_error is an upper bound on the shot noise of each
quasi-probability, the same for every bitstring. Each probability is a sum of the
\(2^k - 1\) Z strings over the \(k\) qubits, weighted \(2^{-k}\), so it is
\(1 - 2^{-k}\) times the bound estimate_standard_errors() gives one Z
string. A marginal carries its own. The bound is loose for unlikely bitstrings, and does
not apply to nearest_probabilities() or counts().
Against the same circuit run whole:
from qiskit.result import marginal_counts
from qiskit.visualization import plot_histogram

measured = circuit.measure_all(inplace=False)
counts = sim.run(transpile(measured, sim), shots=4096).result().get_counts()

plot_histogram(
    [probs.counts(), marginal_counts(counts, [0, 1])], legend=["QCut", "uncut circuit"]
)
Logging#
QCut reports what it decided at INFO, which nothing prints until logging is
configured:
import logging

logging.basicConfig(
    level=logging.INFO,
    format="%(asctime)s - %(name)s - %(levelname)s - %(message)s",
)

logging.getLogger("QCut").setLevel(logging.INFO)
logging.getLogger("qiskit").setLevel(logging.WARNING)
That covers the whole run: which partitions the finder costed and which it kept, whether consolidation was worth it, which cuts were bundled and the gamma that bought, any bundle the device could not take and what it fell back to, how many circuits went into each job and that job’s id, and how a communicating run split its shots between waves.
The job ids are the most important part. A job that fails or stalls on the device can be looked up by its id from the log.